Imperfection for Precision:
Upcycling Imperfect Data for High-Precision Robotic Manipulation

Anonymous Authors

TL;DR

High-precision robot learning depends on expensive task-specific demonstrations, while abundant imperfect data is usually discarded. ε4P upcycles that data with source-dependent flow-time admission: low-precision target-task data contributes at high noise, and high-precision task-mismatched data contributes at low noise. The method changes only flow-time sampling — not the policy architecture or objective.

1. Start With Imperfect Robot Data

High-quality demonstrations for a specific task are costly to collect. Lower-precision data from the same task and precise data from other tasks are more accessible, but naive co-training also transfers their mismatches across the full flow trajectory.

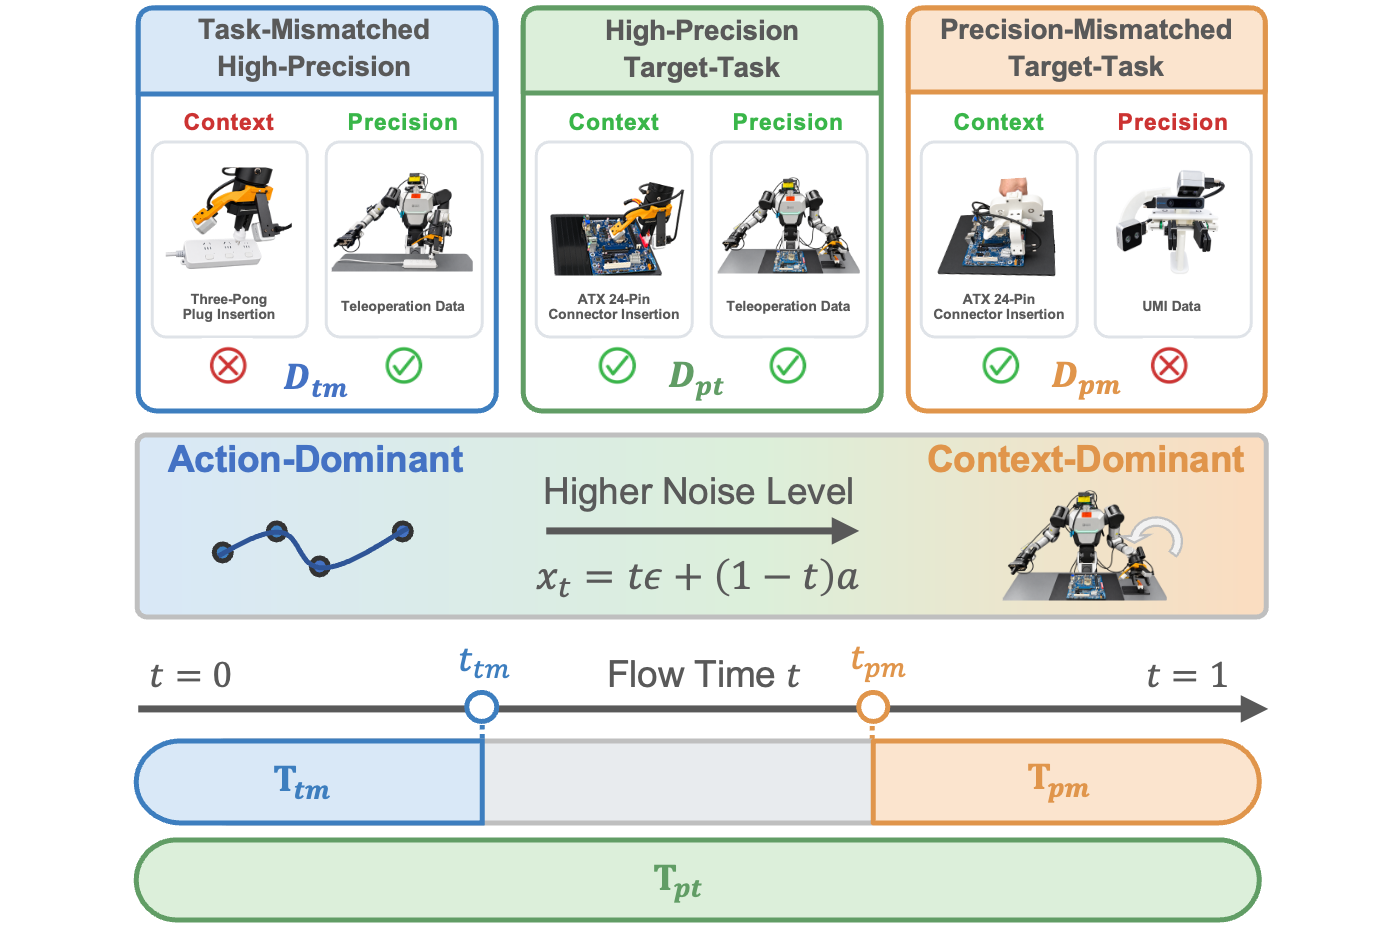
Conceptual overview of three data sources and their source-dependent flow-time admission regions
Conceptual overview.
Three data sources provide complementary supervision.

ε4P keeps the high-precision target-task source active throughout the flow trajectory, while routing each imperfect source only to the region where its useful information remains.

  • (a) High-precision target-task data Dpt. Teleoperation demonstrations supervise the full trajectory.
  • (b) Precision-mismatched target-task data Dpm. UMI preserves target-task context but provides lower-precision actions.
  • (c) Task-mismatched high-precision data Dtm. Auxiliary teleoperation preserves action precision while changing task context.

2. Action-Context Reliance Across Flow Time

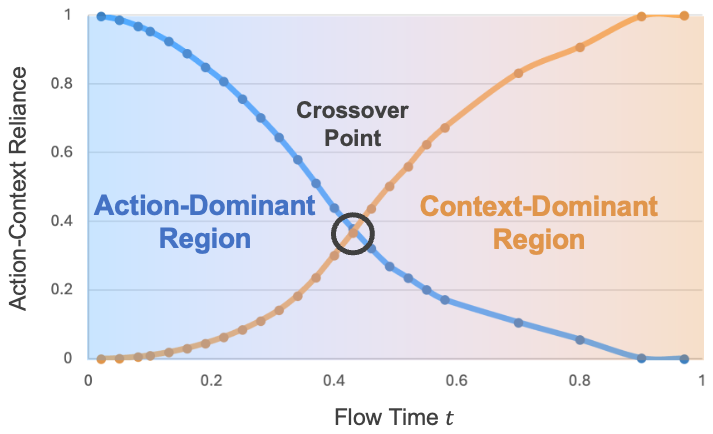
The policy relies more strongly on the noised action input at low flow times and increasingly on task context at high flow times. This transition explains why the two imperfect sources are useful in different regions.

Action and context reliance curves across flow time, with action-dominant and context-dominant regions
Interventional analysis reveals an action-dominant low-flow-time regime and a context-dominant high-flow-time regime, motivating source-dependent admission.

3. Use Flow Time as an Admission Filter

ε4P retains the original source-sampling distribution and changes only the flow-time support assigned to each source.

Dpt High-precision target-task data
Teleoperation; task matched and precision matched.
Tpt=[0,1]
Dpm Precision-mismatched target-task data
UMI; task matched with lower-precision actions.
Tpm=[tpm,1]
Dtm Task-mismatched high-precision data
Teleoperation; precision matched with mismatched task context.
Ttm=[0,ttm]
Action-dominant · t∈[0, ttm]

At low flow time, the policy relies more strongly on the noised action input. Precise demonstrations from a mismatched task can transfer low-level execution skill with limited influence from the mismatched context.

Best source: high-precision, task-mismatched Dtm.
Context-dominant · t∈[tpm, 1]

At high flow time, target-task context remains valuable even when demonstrated actions are less precise. A classifier identifies when noised actions from Dpm and Dpt can no longer be reliably separated.

Best source: target-task, precision-mismatched Dpm.

4. Changes to the Flow-Matching Policy

ε4P is a drop-in training change. Everything stays standard — only source-dependent flow-time sampling changes.

Model architectureNo changes
Flow-matching objectiveNo changes
InferenceNo changes
Flow-time samplerSimple modification
Phase 1 · offline

Estimate Source Boundaries

Find tpm with a flow-time-conditioned source classifier and find ttm with action/context intervention probes on the final post-trained policy.

Phase 2 · training-time

Sample an Admissible Flow Time

  1. Sample a data source using the original source probabilities.
  2. Sample t uniformly from that source's fixed admission region.
  3. Construct the noised action and optimize the standard flow-matching objective.

5. Experiments & Results

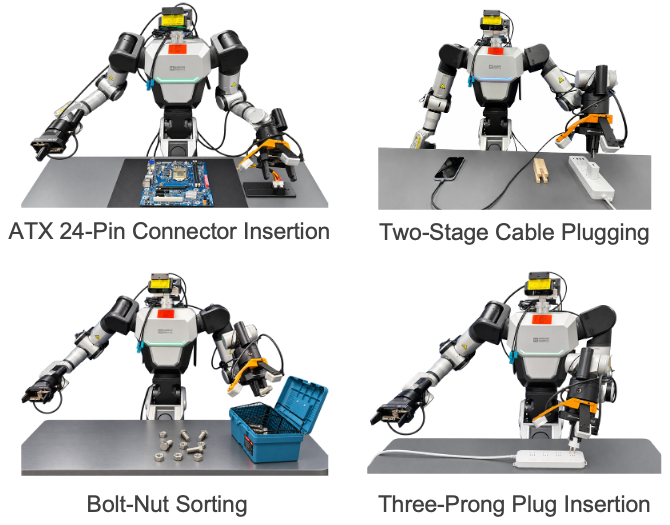
High precision. ε4P is evaluated on ATX 24-pin connector insertion (about 0.2 mm nominal clearance) and two-stage cable plugging (about 0.3 mm lateral clearance).

Generality. Bolt–nut sorting tests whether the method also helps on a coarse-grained manipulation task. All policies use the same architecture, checkpoint, optimizer, source probabilities, and training budget.

Real-robot task setups: ATX 24-pin connector insertion, two-stage cable plugging, bolt–nut sorting, and three-prong plug insertion
Controlled real-robot experiments

RB-Y1 platform · 60 trials per target task

ATX connector insertion

Joint admission reaches 80.0% success.

Native co-training with both imperfect sources achieves 38.3%. ε4P routes the same sources to complementary windows and improves success to 80.0%.

Two-stage cable plugging

Full-task success rises to 88.3%.

Compared with 78.3% using target-task data alone and 33.3% under native co-training with both imperfect sources.

Bolt–nut sorting

Coarse manipulation reaches 91.7%.

The result shows that source-dependent admission is not limited to sub-millimeter insertion tasks.

Why Flow-Time Admission Matters

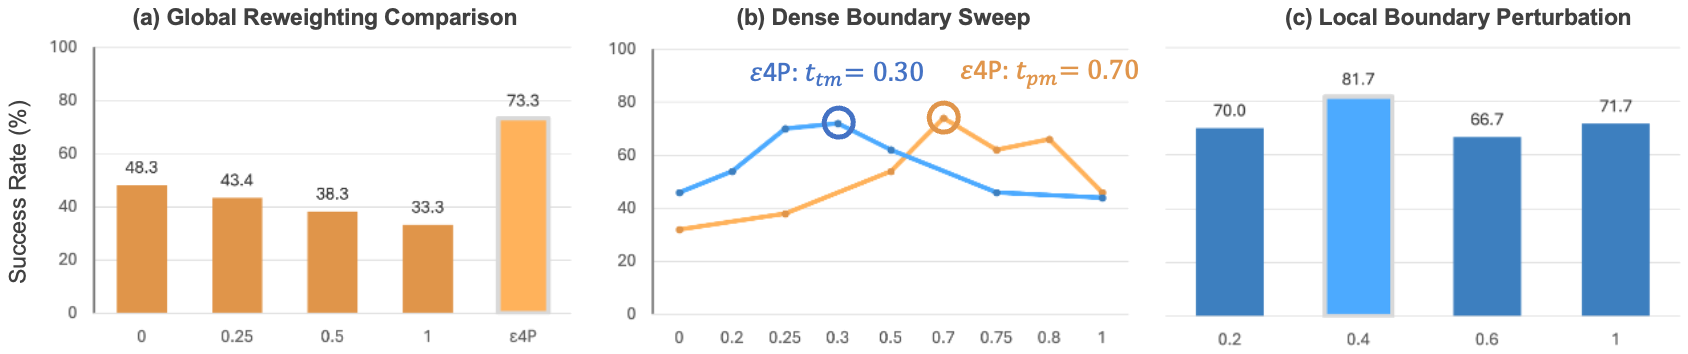
Figure 5 compares flow-time admission with global loss reweighting and checks whether the identified boundaries align with strong downstream performance.

Figure 5: (a) global loss reweighting on ATX, (b) dense admission-boundary sweeps on ATX, and (c) local boundary perturbation on Cable
Figure 5. Global reweighting and admission-boundary validation. Select the figure to view it at full size.

(a) Global Reweighting on ATX

Reducing the loss weight of Dpm limits the harm from native co-training, but no tested nonzero weight exceeds the Dpt-only baseline (48.3%). ε4P keeps wpm = 1 and changes only its flow-time support, reaching 73.3% success.

(b) Boundary Sweeps on ATX

The identified boundaries, ttm = 0.30 and tpm = 0.70, lie in the high-performing regions of the dense sweeps. This supports the complementary admission windows for task-mismatched and precision-mismatched data.

(c) Local Validation on Cable

The identified ttm = 0.40 reaches 81.7% full-task success, compared with 70.0% at 0.20 and 66.7% at 0.60. It is the best of the tested settings, providing local validation on a second task.

Admission boundaries are estimated from offline diagnostics. The downstream sweeps and perturbations validate those choices; they are not used to select the boundaries.

Key takeaway: stop accepting or rejecting imperfect data globally.

  • Native co-training uses every source at every flow time and learns both useful and harmful supervision.
  • Global reweighting reduces how much a source contributes but cannot isolate where it helps.
  • ε4P changes the question from which data to keep to when each source should contribute.